Not every text field in a survey needs the same level of processing. Some fields contain critical data that must be verified character by character, while others hold optional comments that only need a quick scan. PaperSurvey offers eight recognition modes so you can balance accuracy, verification effort, and processing limits for each field individually.
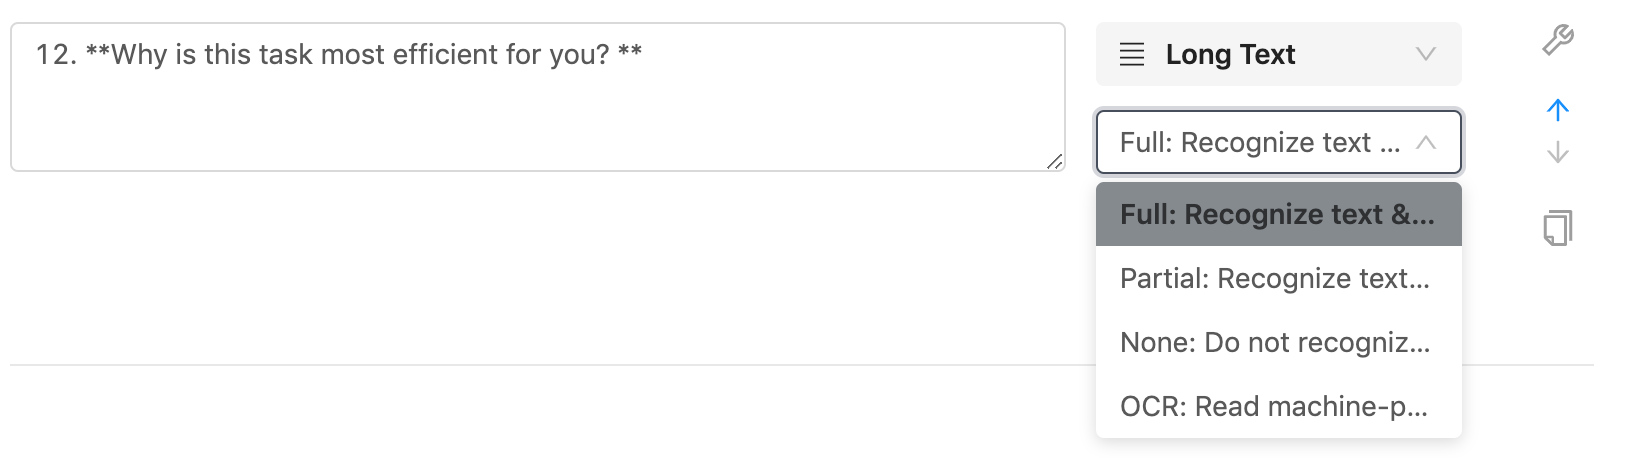
Text recognition modes
Good accuracy
The recommended mode for longer text fields. PaperSurvey recognizes handwritten text and automatically accepts responses where confidence is at least 90%. Responses below that threshold are flagged for your review.
Responses that meet the confidence threshold can be accepted automatically. Confidence is a model score, not a measured error rate, so accepted responses can still contain mistakes. Use the Review tab to check a sample of them against the original scans.
This is the default mode for Long Text fields.
For short, high-value fields like names, email addresses, or ID numbers, a single wrong character can make the response unusable. Use Verify always when each value must be checked by a person.
Best for: Open-ended feedback, comment fields, and general survey text fields where minor recognition errors are acceptable.
Verify always
PaperSurvey recognizes the text but flags every response for manual verification, regardless of confidence level. Unlike Manual mode, text is still recognized automatically, which means the recognized text is pre-filled when you verify, saving you from typing each response from scratch.
Best for: Fields where every response must be reviewed by a person but you still want recognition to speed up the verification process.
100% accuracy
Despite its name, this mode does not guarantee error-free transcription. It auto-accepts recognized text only when the system returns its maximum confidence score; lower scores are flagged for manual verification. Use Verify always if every response needs human review.
This is the default mode for Short Text and Email fields. Expect more responses to land in your verification queue with this mode. Encourage respondents to WRITE IN CAPITAL LETTERS for better recognition accuracy.
Best for: Names, email addresses, ID numbers, codes, and any field where a single wrong character would cause problems.
Custom accuracy
This mode lets you set your own confidence threshold for auto-acceptance. Responses at or above your chosen percentage are accepted automatically, while those below are flagged for review.
The threshold defaults to 90% and can be set to 70%, 80%, 90%, 95%, or 97%. Lower thresholds allow more responses to be accepted automatically. Higher thresholds route more responses to review; they do not guarantee correctness.
Best for: Situations where the default 90% threshold does not match your accuracy requirements, or when you want fine-grained control over the automation balance.
Recognize, never flag
PaperSurvey recognizes the text and accepts all responses automatically, regardless of confidence level. This mode does not flag responses based on recognition confidence; separate validation rules may still require review.
Use this option only when automatic acceptance suits your review requirements.
Best for: High-volume surveys where speed matters more than catching every error, supplementary comment fields, and preliminary analysis.
No recognition
Skips text extraction entirely. Responses are accepted as blank, though the original handwriting remains visible in scanned images.
Best for: Optional comment fields you do not plan to analyze, surveys where only quantitative data matters, and fields where you want to preserve your recognition quota.
Manual
Skips automatic recognition and flags every response for manual entry. You type each response yourself while viewing the scanned image.
This mode does not count against your recognition limits, making it useful when you have exceeded your monthly quota or when handwriting is too complex for automated recognition.
Best for: Complex handwriting styles, fields requiring human interpretation, and situations where you have reached your recognition limit.
OCR (machine-printed text)
A specialized mode that reads only machine-printed characters. It ignores handwritten content entirely and uses optical character recognition optimized for typed or printed text.
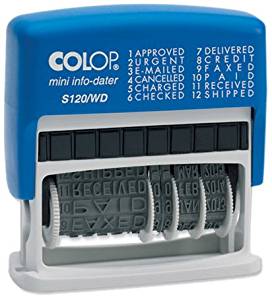
Best for: Pre-filled form fields, date stamps, info-daters, printed label stickers, and any field containing machine-generated text.
Number and date recognition
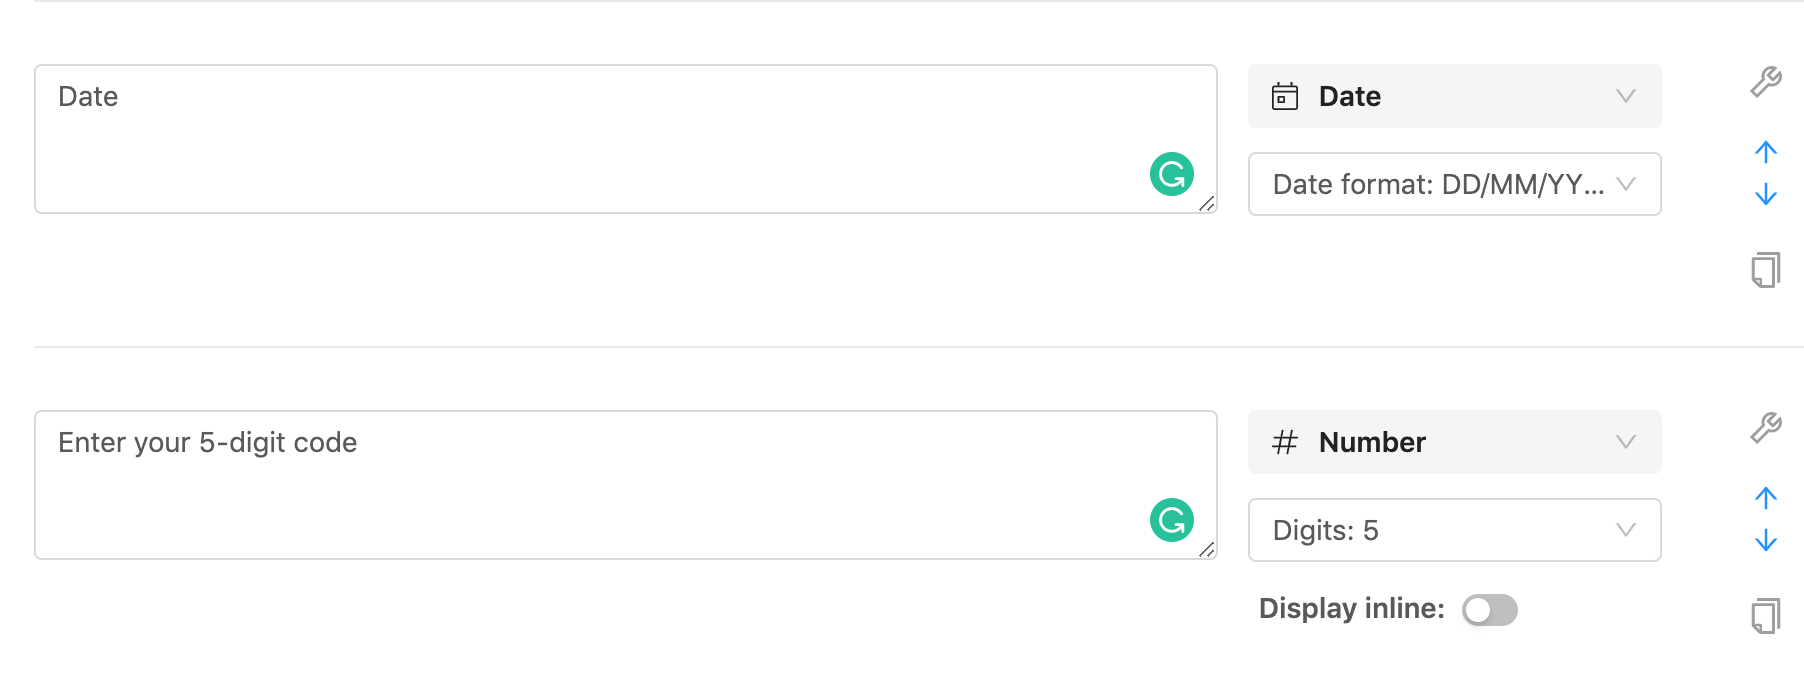
Number and Date question types use specialized digit recognition optimized for handwritten numerals. This technology is separate from general text recognition. Number fields only read digits. If your identifier contains a mix of numbers and letters, use a Short Text field instead.
Key advantages:
- Digit-specific recognition for numeric answers
- Digit boxes and dates do not use handwriting credits. Free-form Number fields are also included unless their width is set above 8 cm.
- Automatic validation for dates
- Recognized values available for review alongside their scans
Best practices for number fields
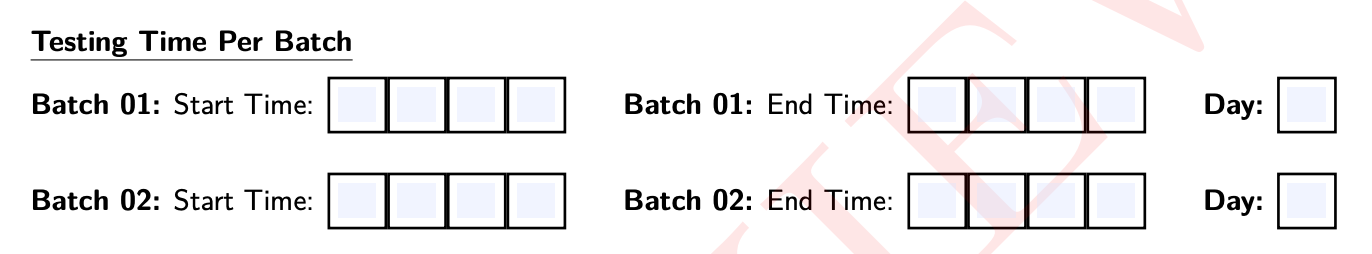
Recommended: Fixed digit boxes. Specify the maximum number of digits expected (up to 20). This provides individual boxes that separate each digit. A free-form option without digit boxes is also available. Test the layout with representative handwriting before collecting a full batch. Number fields can also add two decimal places with the Decimal setting.
Changing modes on existing surveys
When you change the recognition mode for a field that already has processed responses, PaperSurvey re-evaluates all existing responses against the new threshold. Responses that were previously flagged may be automatically accepted, and responses that were previously accepted may be flagged for review.
You will see a preview of how many responses will be affected before confirming the change. You can also choose to save the new mode for future responses only, leaving existing data untouched. Responses you have already verified manually are never changed by a re-evaluation.
Choosing the right mode
Long text fields default to Good accuracy and email fields default to 100% accuracy. These defaults handle the majority of cases well. From there, adjust based on your needs:
- Data criticality. Choose Verify always when every value must be checked by a person.
- Volume. Use Recognize, never flag when processing thousands of responses and speed is the priority.
- Recognition limits. Choose Manual or No recognition to preserve your monthly quota for the fields that matter most.
- Response type. Select OCR for machine-printed text instead of handwriting.
- Fine-tuning. Use Custom accuracy when 90% is not quite the right threshold for your use case.
- Mandatory review. Use Verify always when every response needs human review but you still want recognition to pre-fill answers.
Monthly recognition limits
Automatic text recognition uses one handwriting credit per answer area on each scanned response, regardless of the number of words or characters. Number fields with digit boxes and dates do not use handwriting credits. Free-form Number fields use one credit per answer only when their width is set above 8 cm; numbers written in ordinary Short text or Long text fields use a text recognition credit. Automatic second reads of numbers in the included numeric paths do not add handwriting usage. Page processing counts separately.
Fields detected as blank before text recognition and answers entered in Manual or No recognition mode do not use handwriting credits. Reprocessing a text answer can use another credit. If enabled, each completed check for writing outside a Long text box uses one additional credit.
Your monthly allowance is used first, followed by any purchased extra credits. Limits reset on your billing cycle. See pricing for a worked example.